MAI Image Series Models
I am a core contributor to the MAI Image Series Models, focusing on post-training. My work spans reward model design, vision-language model RL for prompt enhancement, RL for captioning models, and diffusion RL.
MAI-Image-2.6 reached #2 on Text-to-Image Arena, with a score of 1,336 at release.
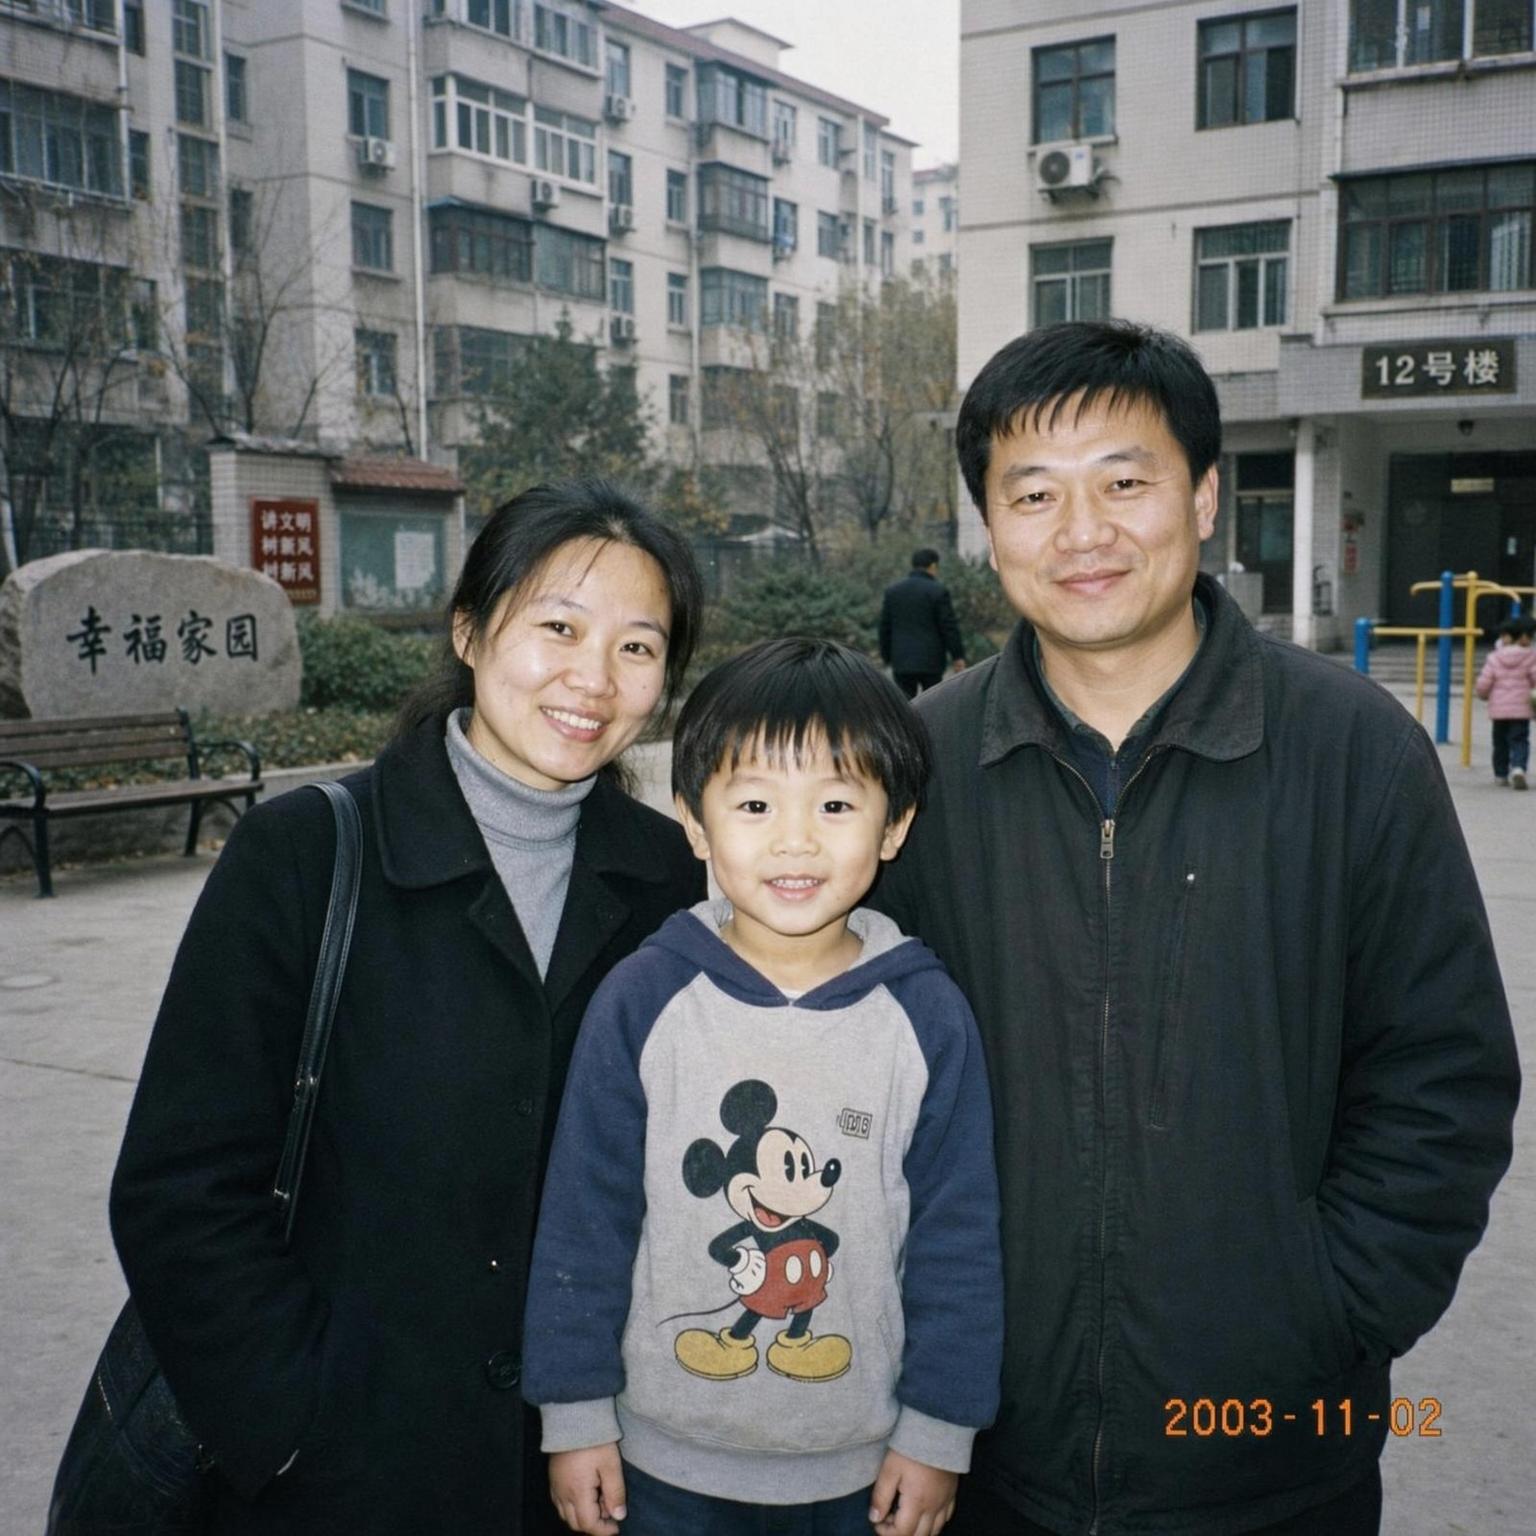
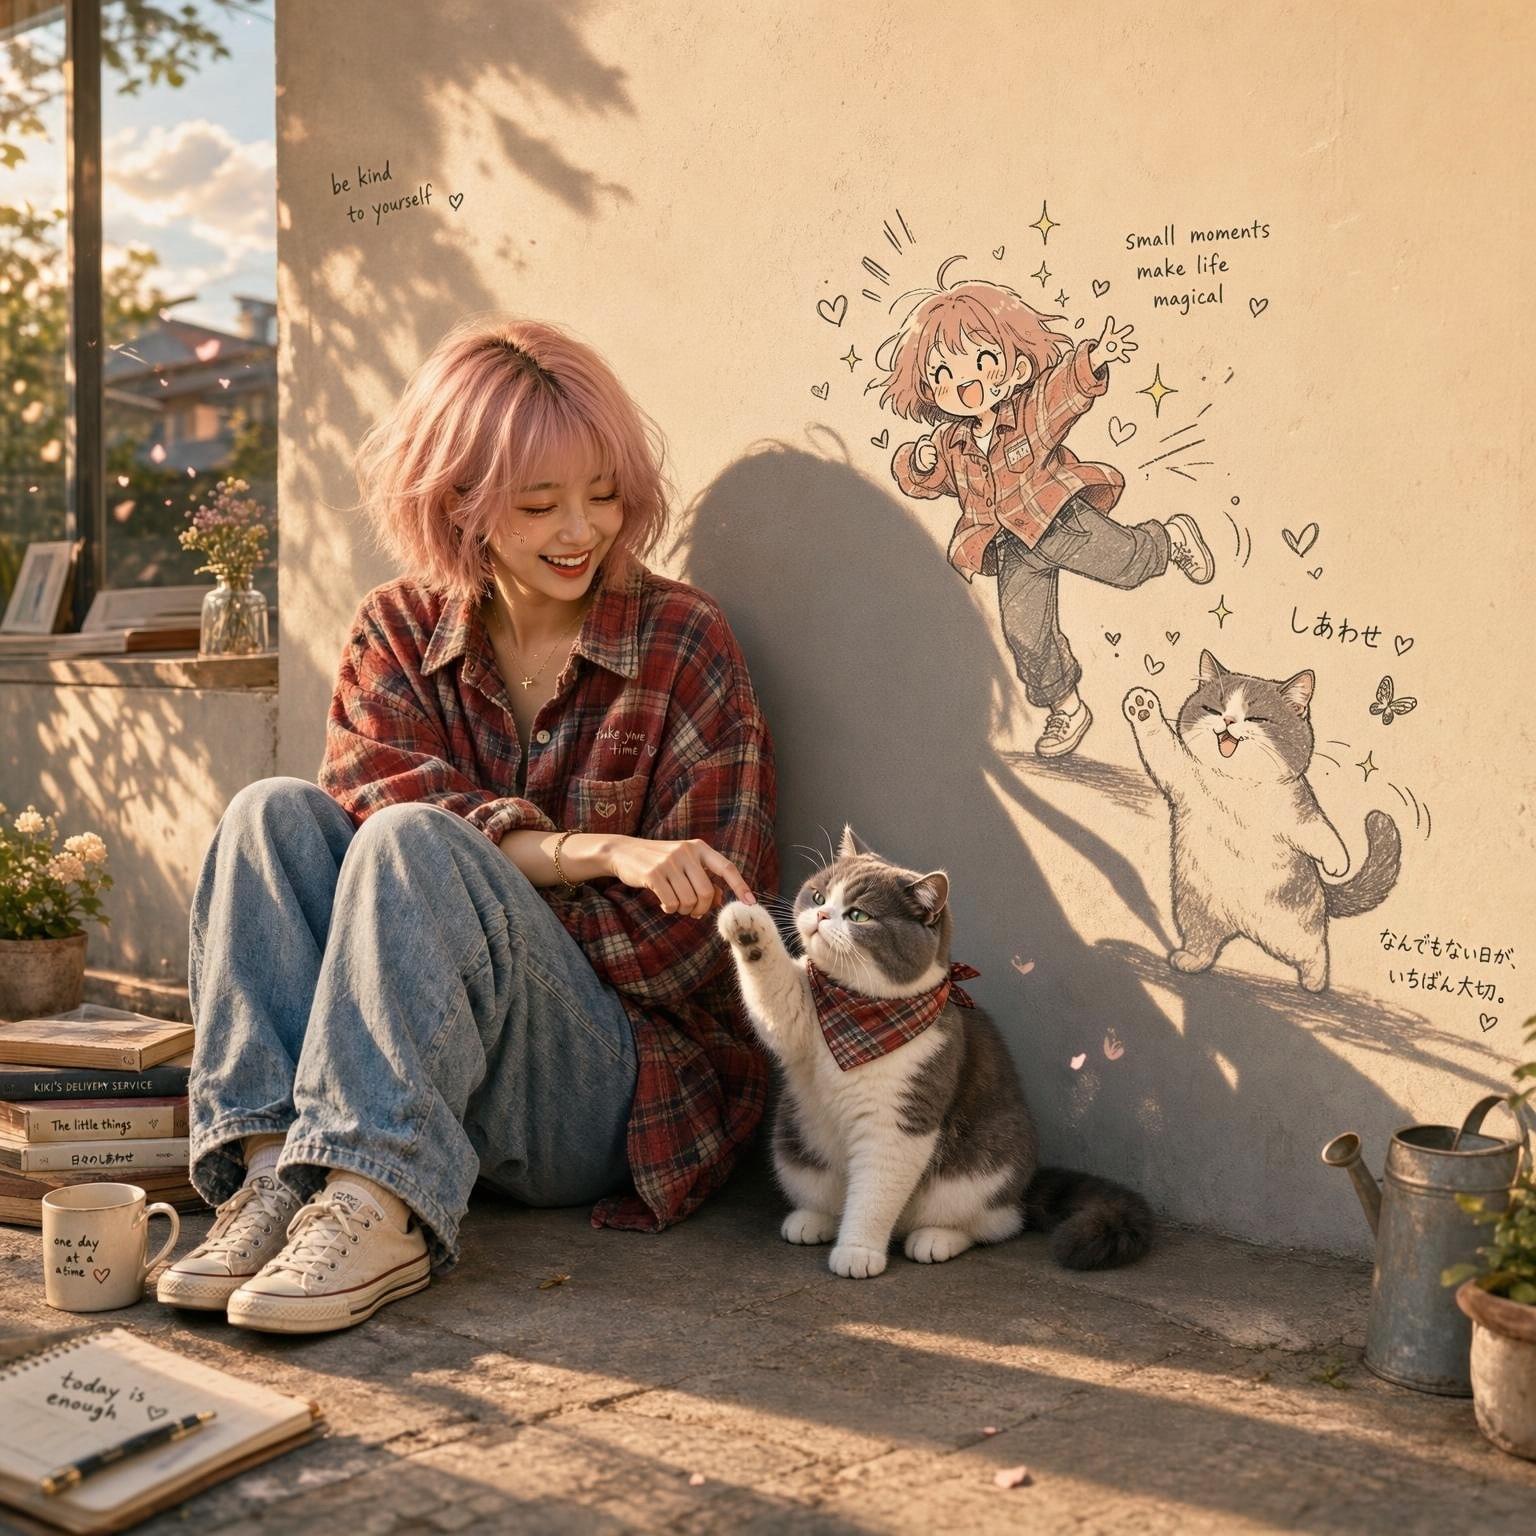
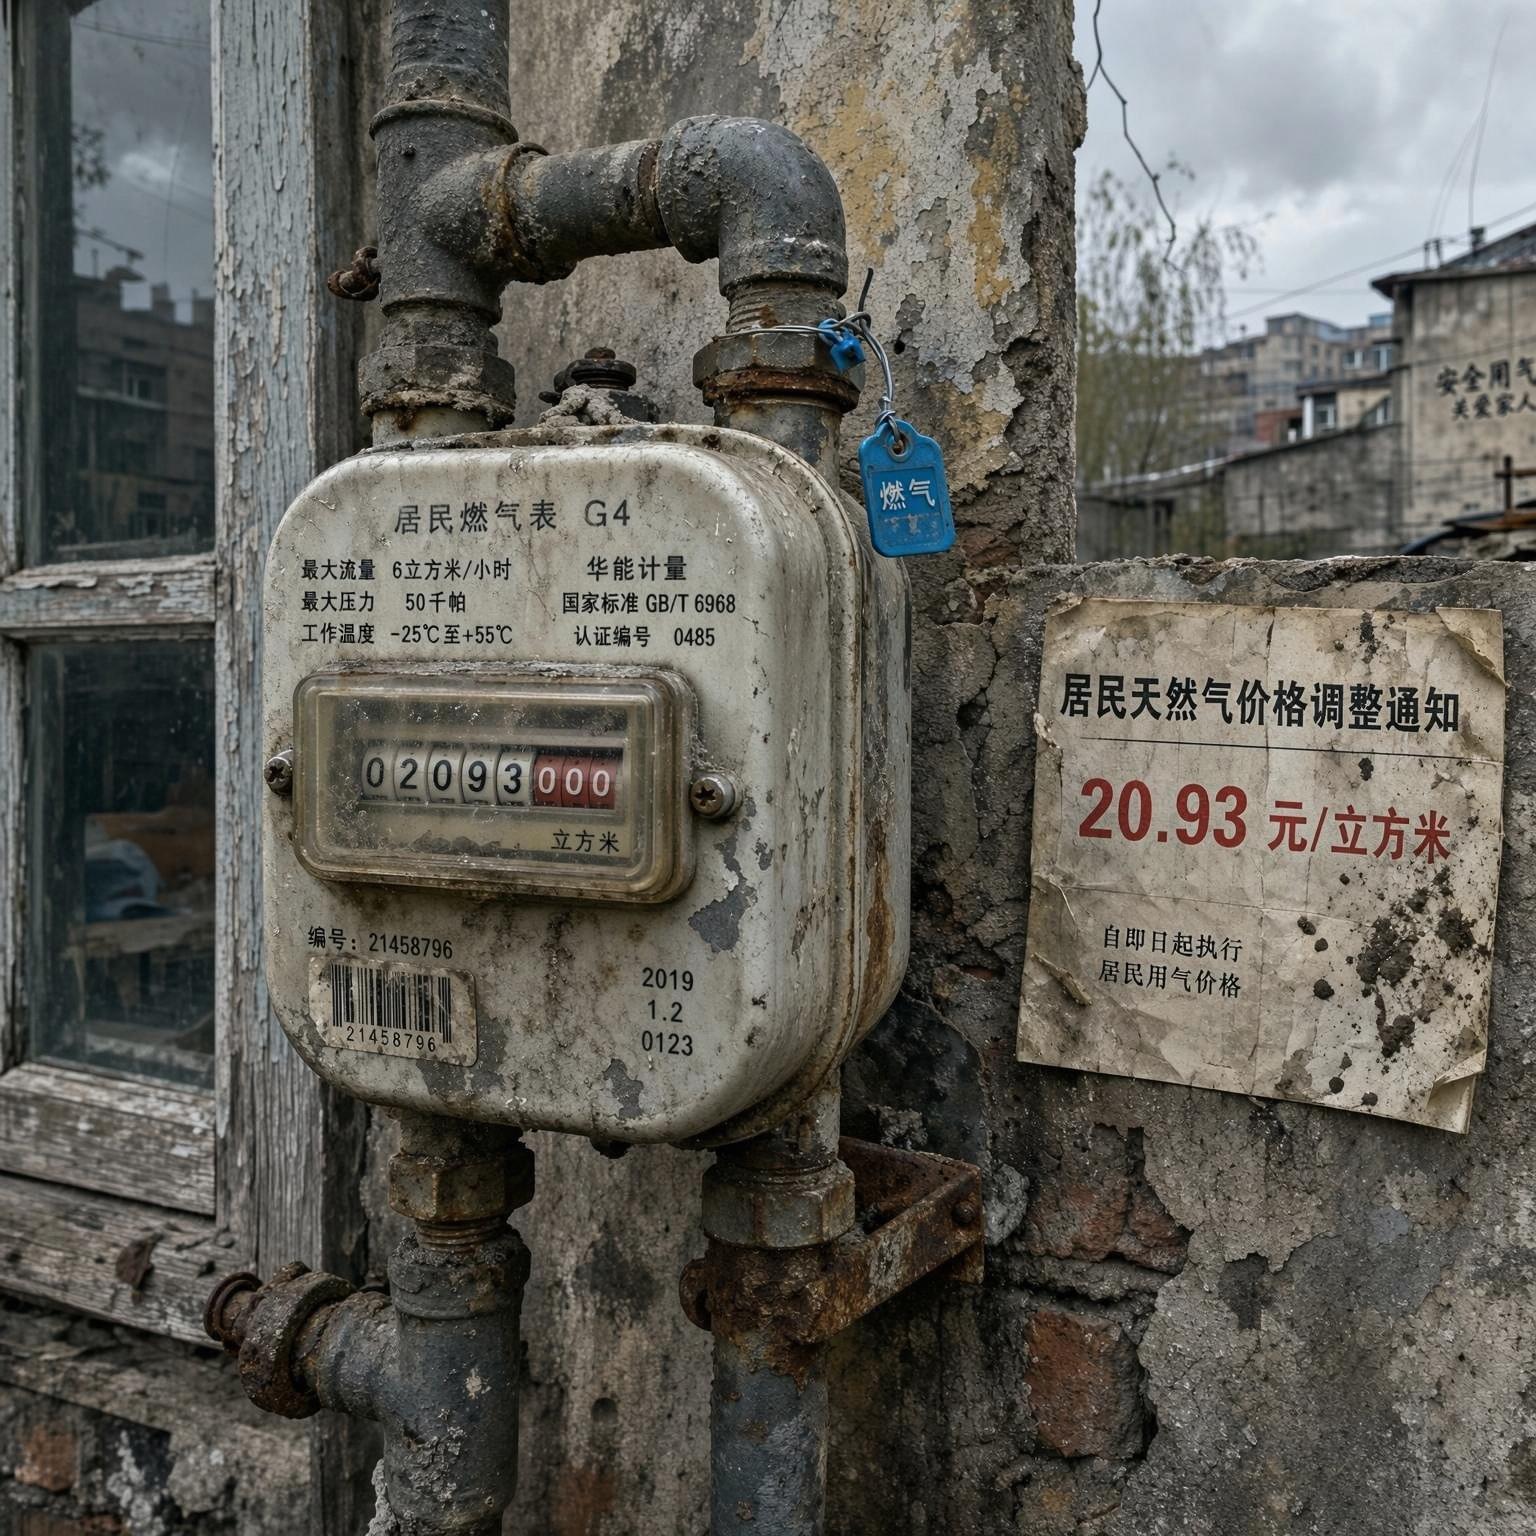
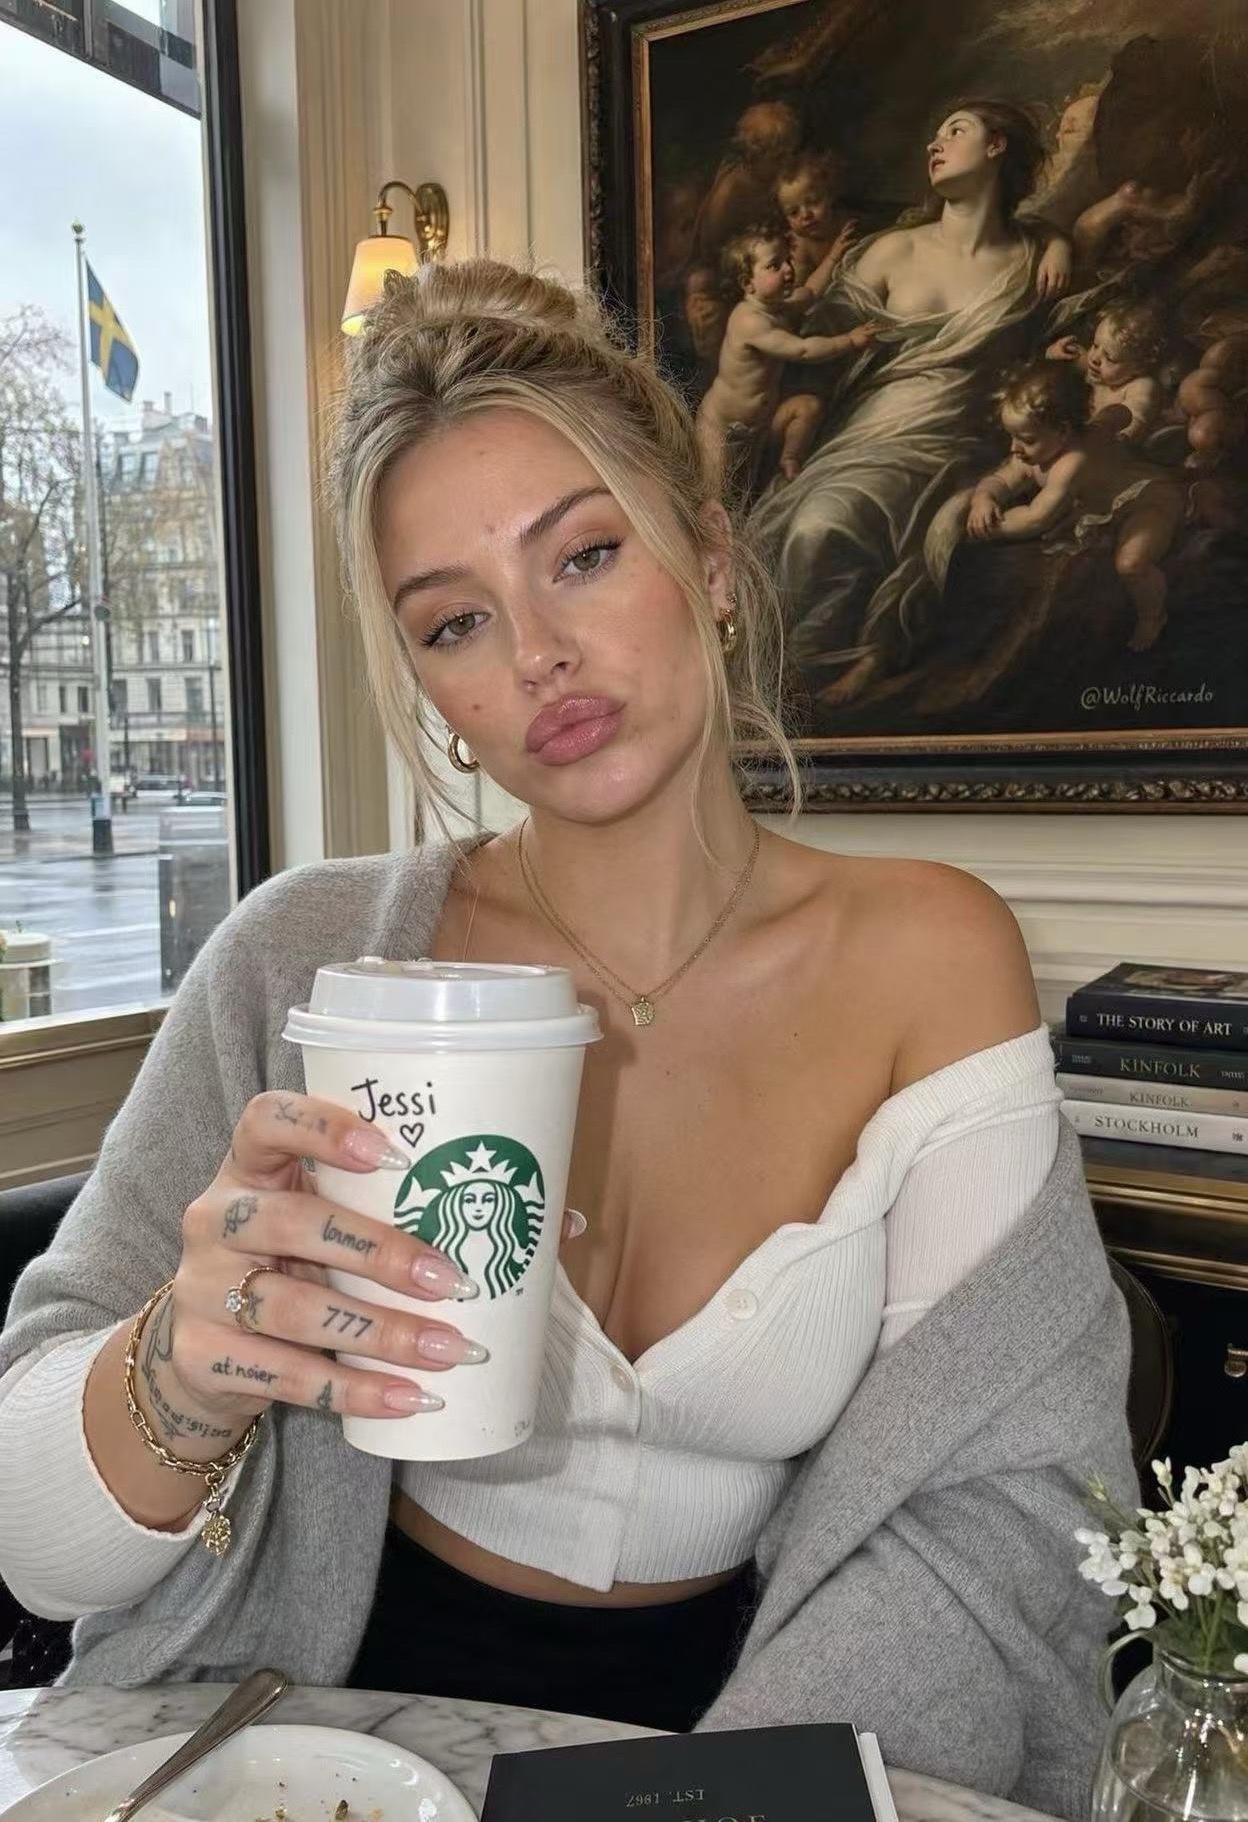
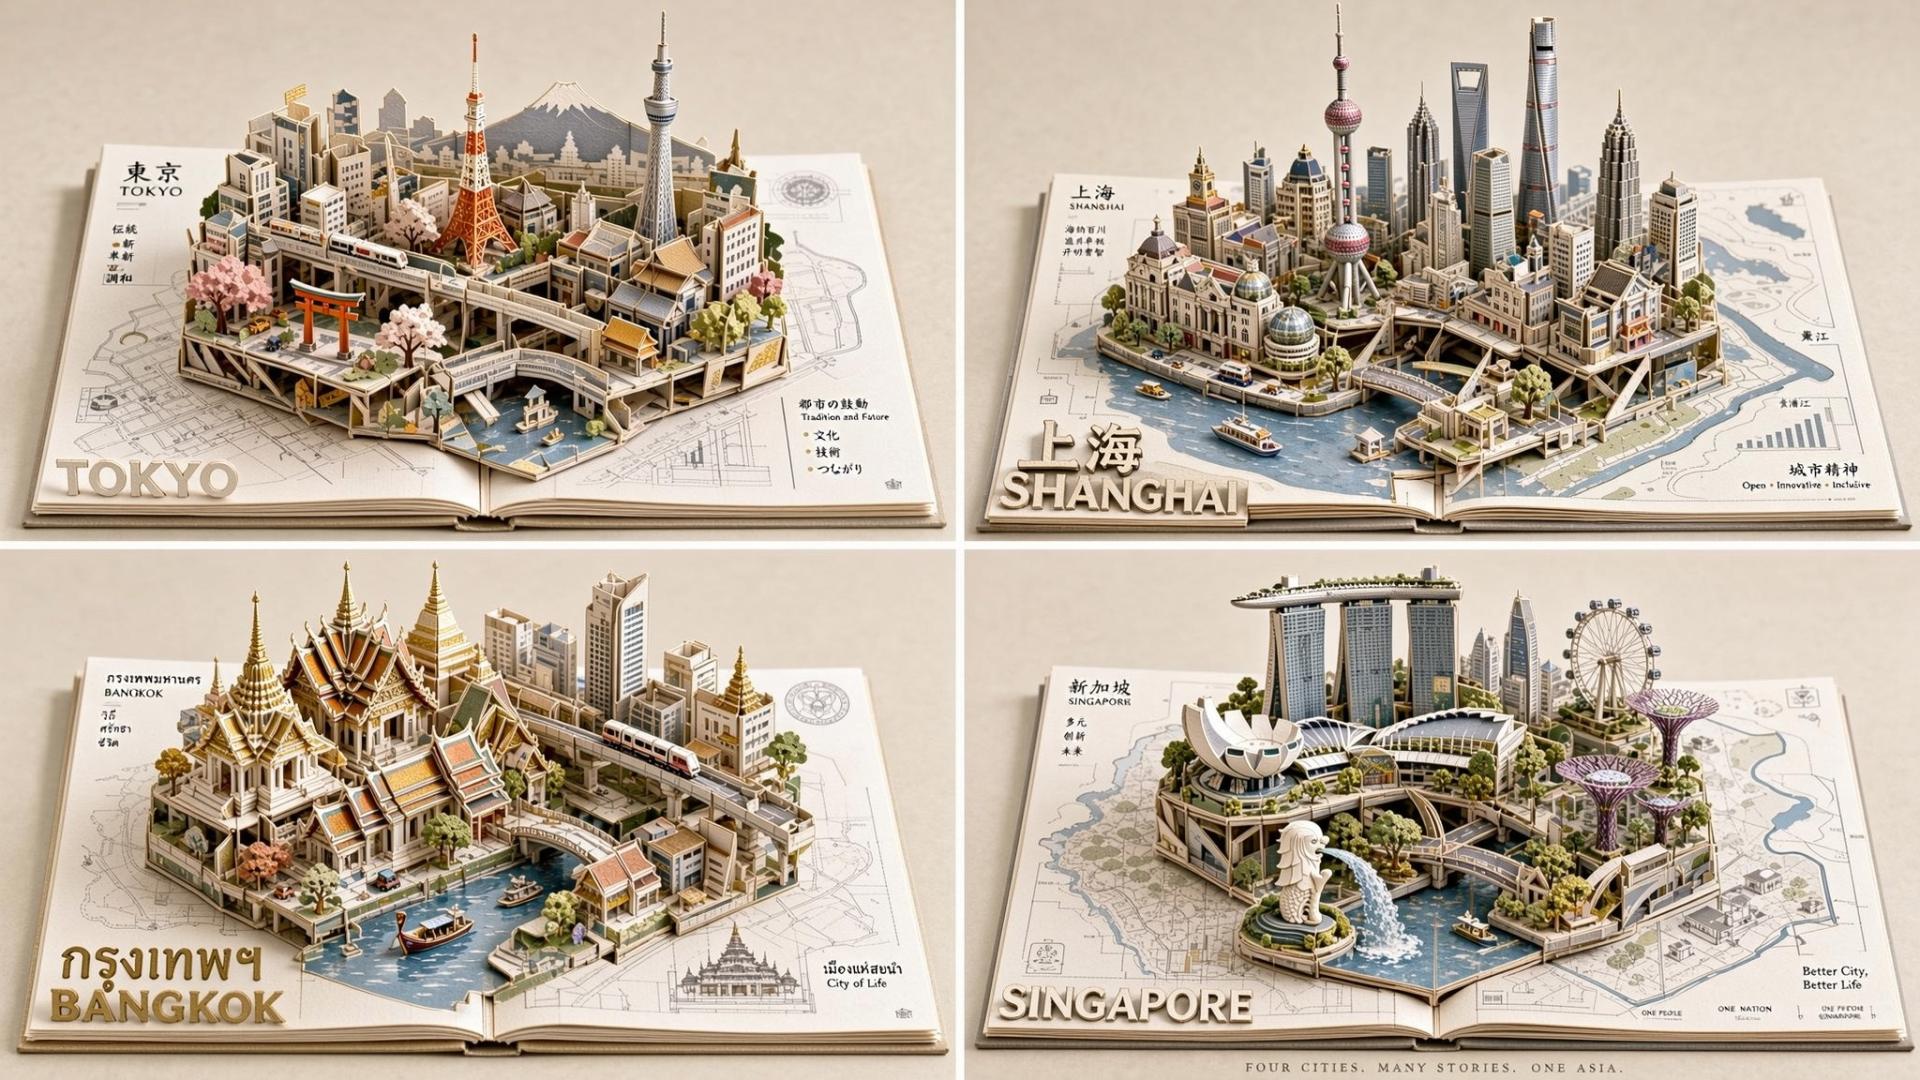
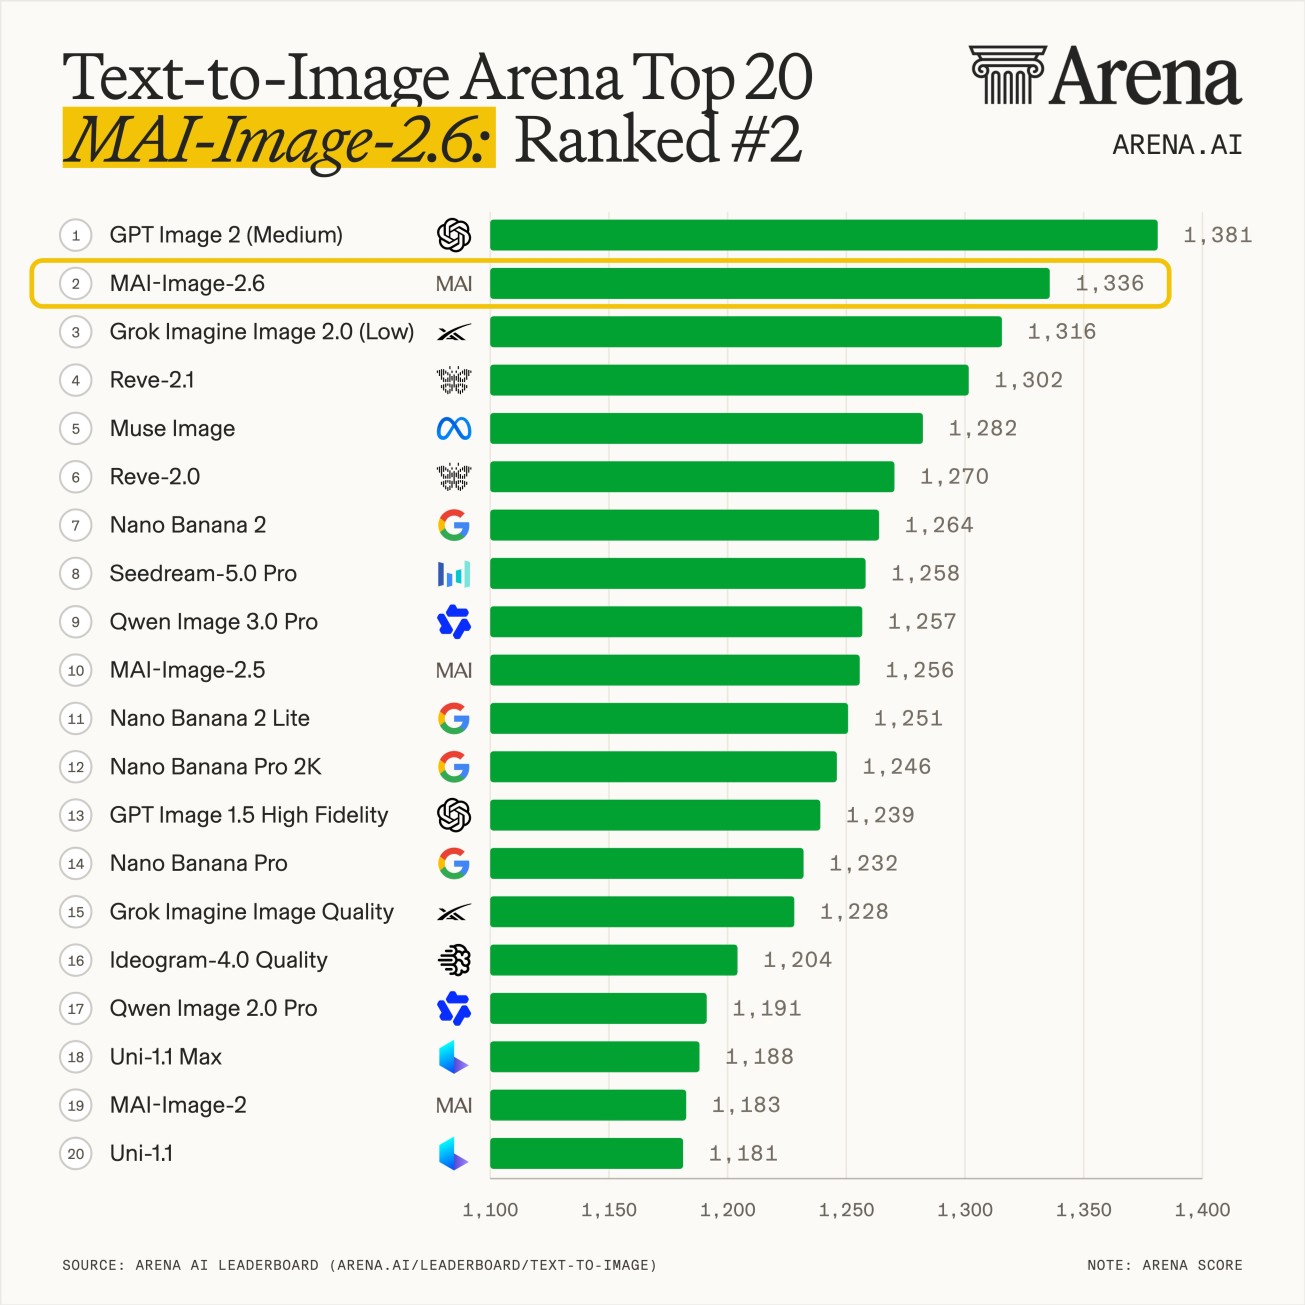
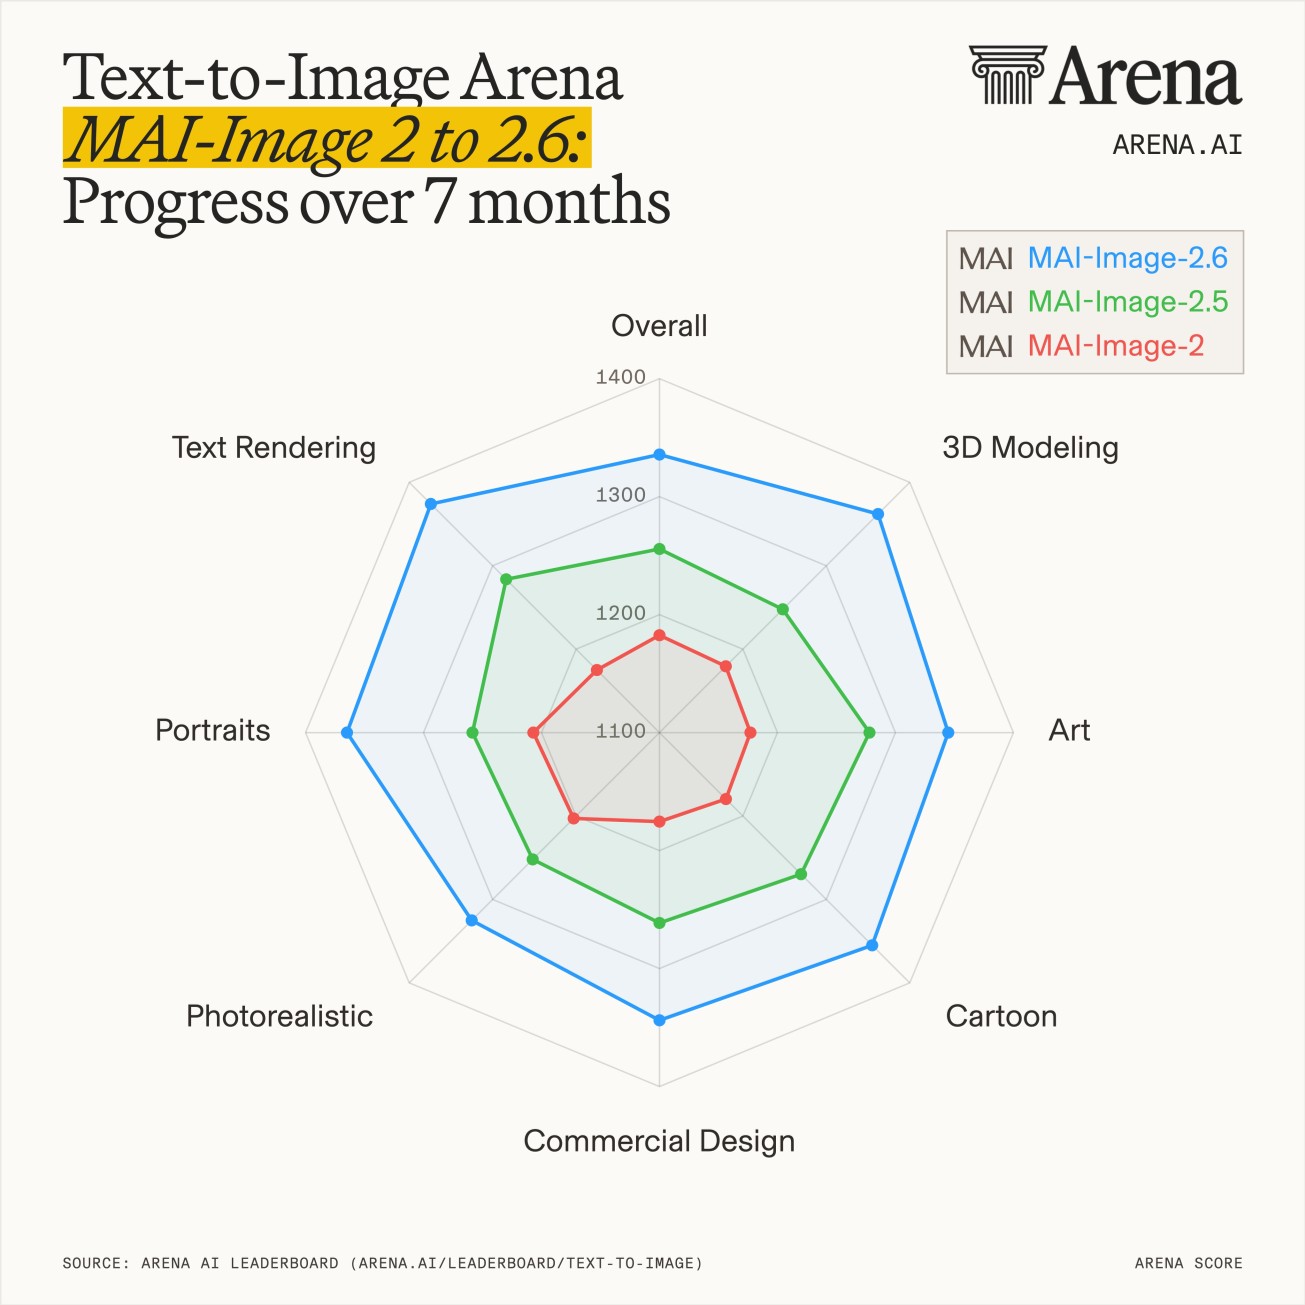
Arena release snapshot · Click an image to enlarge · Source ↗
Earlier Arena results
The 2.5 Preview debuted at #3 on Text-to-Image Arena, with a score of 1,254. This earlier release snapshot precedes the 2.6 chart above.
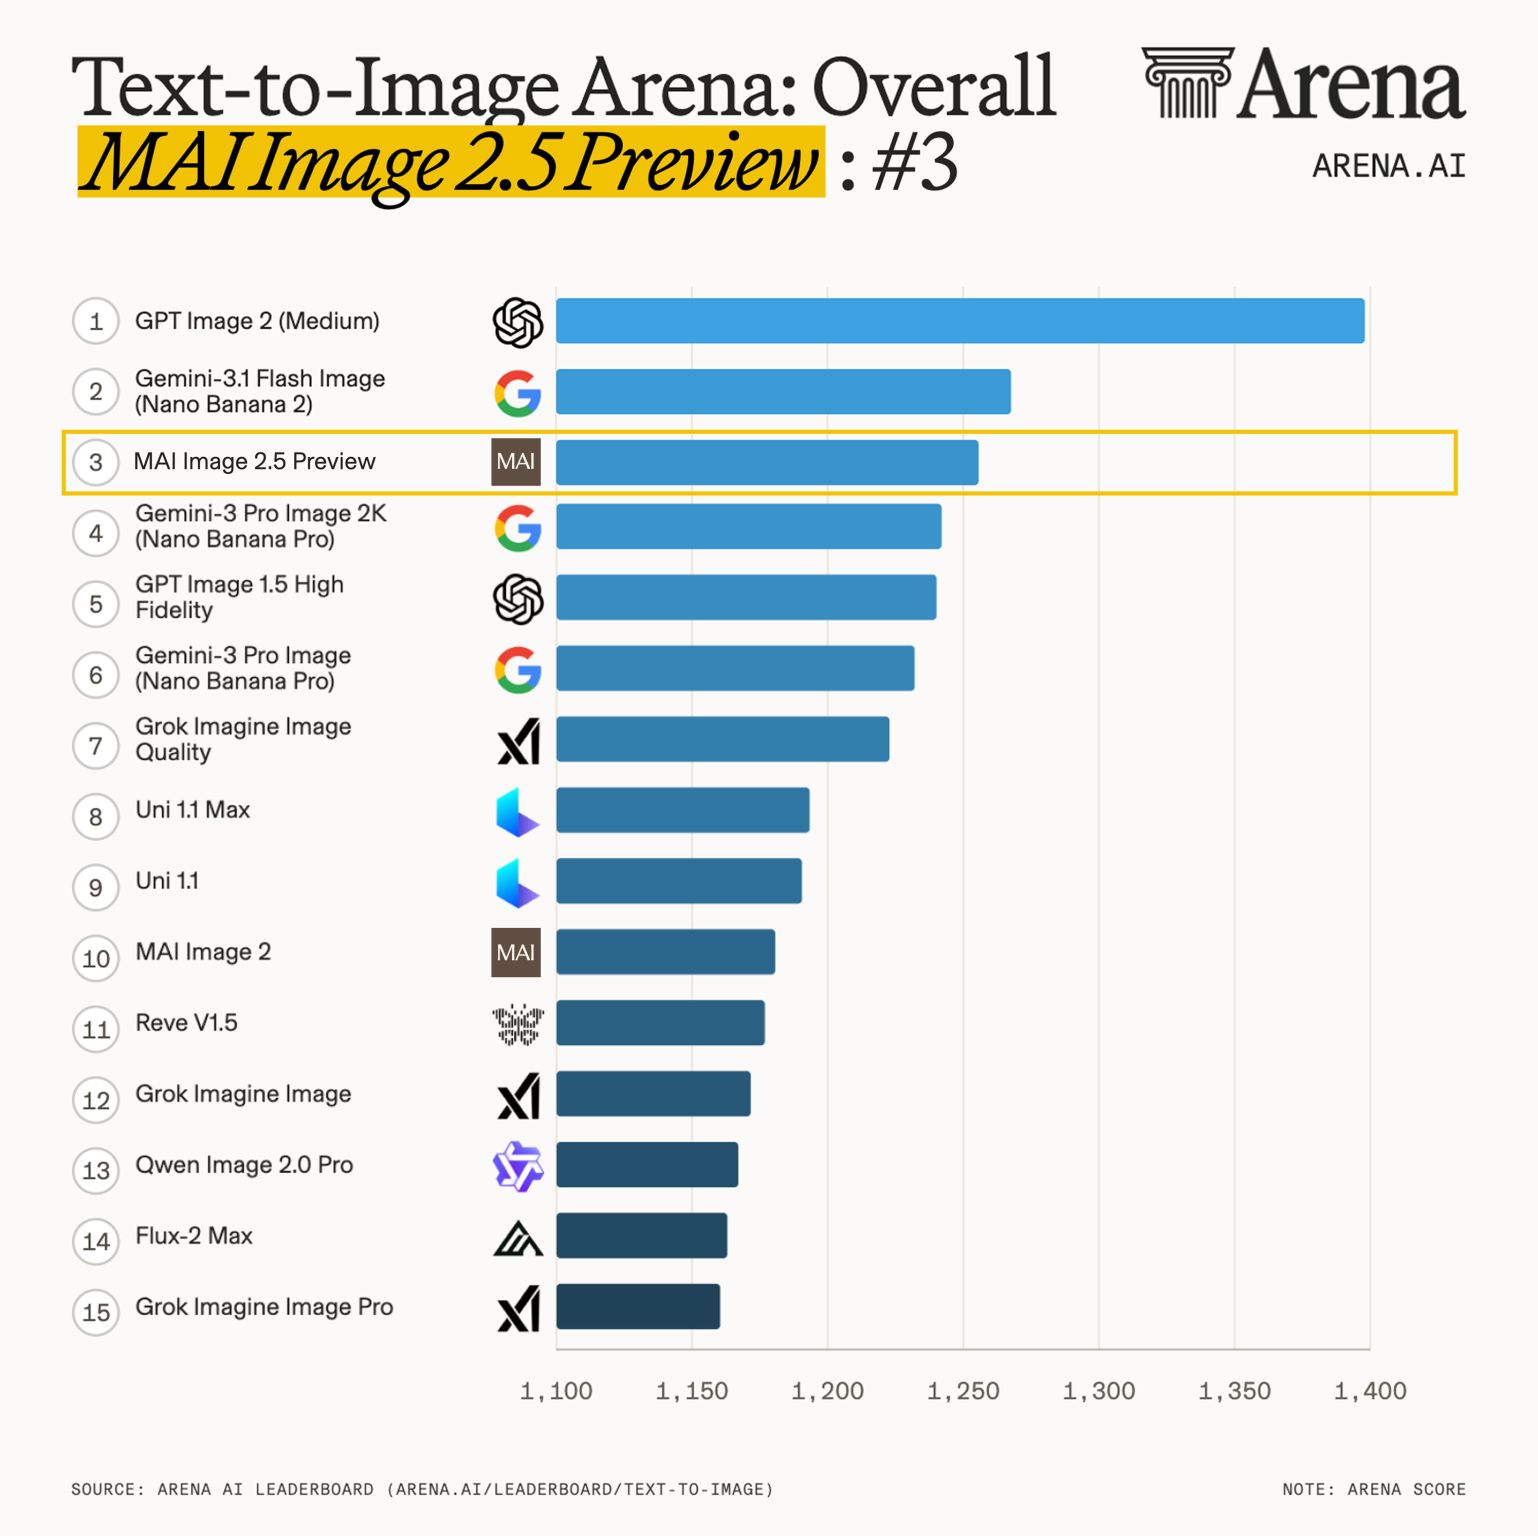
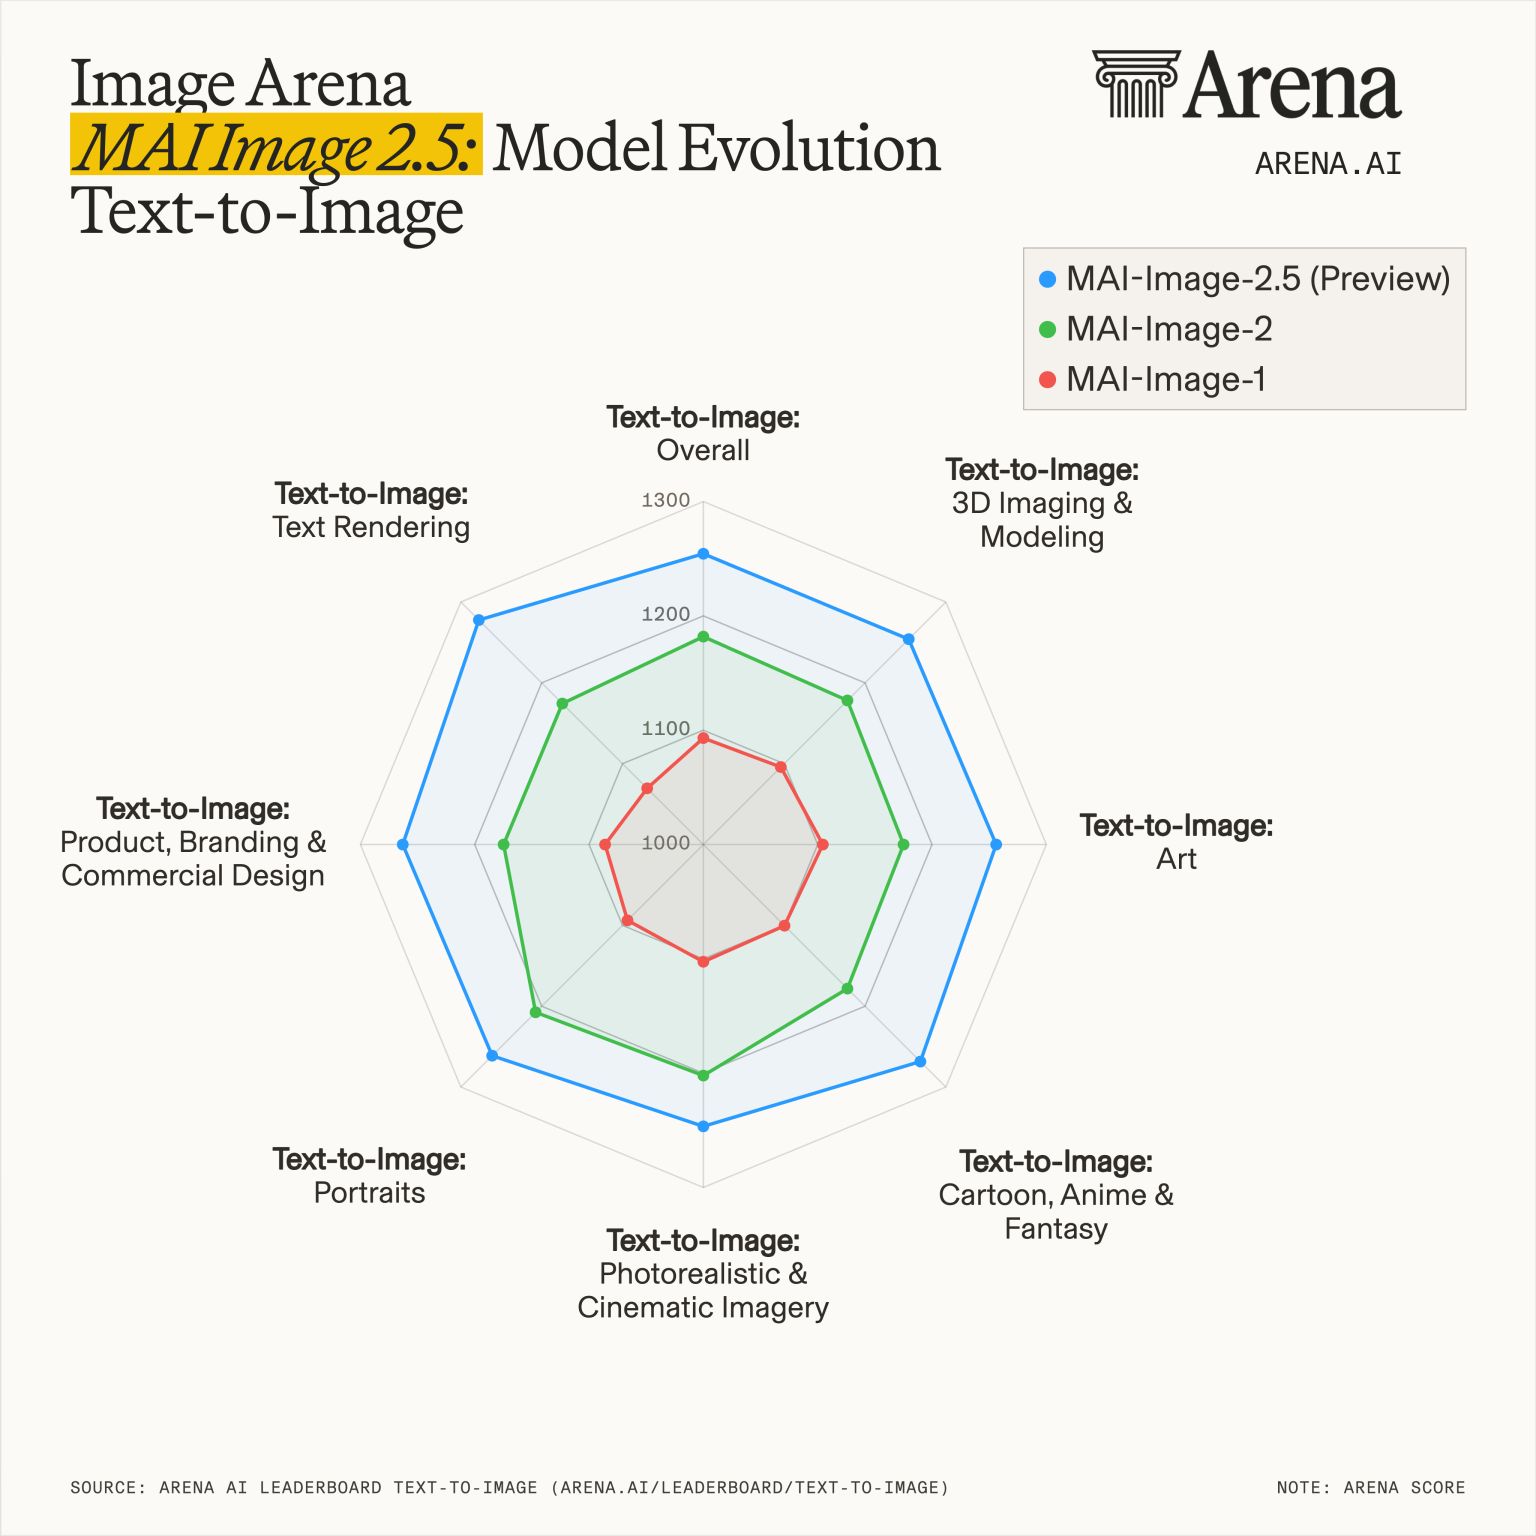
Earlier release snapshot · Click an image to enlarge · Source ↗